Hire Data Engineers
Trusted By 350+ Businesses Worldwide
Hire dedicated data engineers from SysGears to build scalable, reliable infrastructure for your business operations. We are a team of 110+ professionals, specializing in custom software, data engineering, and AI development. Whether you want to build a data platform from scratch, modernize your existing solution, or strengthen your team with senior data engineering expertise, SysGears will readily help you.
Data Engineers Not Just Sourced For Your Needs. Trained For Your Needs.
SysGears is neither a staffing agency nor an intermediary that sources and vets specialists for clients. Instead, we build our own team of data engineers using a holistic talent development framework. We find the best specialists on the market, train them according to our quality and delivery standards, and support their continuous professional growth.
This way, you get professionals who deliver high-quality software, work according to established standards, and grow their skills proactively.
Our Engagement Models
Dedicated Team
Hire a dedicated data engineering team from SysGears to cover this workflow from start to finish. Our specialists seamlessly integrate with your development processes and work under your in-house tech leadership.
Staff Augmentation
Hire remote data engineers to balance workloads in your in-house team. We can take on routine tasks, including maintenance, assist you during releases, and provide technical leadership when needed. You can engage our data engineering experts full-time or part-time, for short-term assignments, or on the long-term basis.
Full Outsourcing
If data processing is core to your software, you can fully delegate your project to SysGears. We can assemble a cross-functional team to handle the development lifecycle end-to-end, from ideation to deployment.
Simple Steps to Hire Data Engineers at SysGears
Let’s Connect
Write to us through the contact form, an on-page chat with our sales manager, or email info@sysgears.com, and we will connect with you as soon as possible. Alternatively, you can book a meeting directly in our calendar. Before you reveal any sensitive project details, we sign an NDA.
Share Your Needs
First, we discuss your staffing needs and project goals: sought expertise, technology stack, hiring urgency, and any other nuances and restrictions.
Select Data Engineers for Hire
After analyzing your requirements, we recommend the best-fitting data engineers from our team. You can review their CVs, interview them, assign a test task, or otherwise verify their expertise. All our data engineers are senior software developers who design and implement reliable and scalable data workflows day-to-day.
Onboard New Team Members
Our expert data engineers are trained to quickly adapt to the team’s workflows, which minimizes onboarding time. This process takes from two weeks to one month, depending on your project’s context.
Get Ongoing Support
Our data engineers become fully integrated with your team. You communicate with them directly, and they participate in discussions, daily standups, demos, and other activities that support your day-to-day work. At the same time, SysGears representatives stay in touch to collect feedback, address concerns, and provide support whenever needed.
Hire Data Engineers for Your Business Needs

Data Platform Architecture and Development
Our data engineers design and implement scalable data platforms that make analytics projects faster and more reliable. We develop our solutions – data lakes, lakehouses, or warehouses – around your actual use cases, data volumes, and business requirements.

Data Pipeline Development
We build and maintain reliable ETL/ELT pipelines to integrate data from multiple sources – CRMs, APIs, databases, and cloud storage – and prepare it for further business use. Our engineers design pipelines that scale along with your growing data volumes and provide strong security through encryption, access controls, and proper credentials management.

Data Engineering For AI/ML
We help prepare your business data for AI/ML model training. Our engineers implement feature engineering workflows, embedding pipelines, and vector data storage to support machine learning applications, semantic search, and RAG workflows.

Real-Time Data Processing and Streaming
Our data engineers have extensive experience implementing real-time data processing for event-driven applications and streaming analytics. From customer-facing apps like an online fitness platform to internal analytics tools, we build robust pipelines that ingest and transmit data with minimal latency.

Data Quality Engineering
We help maintain accuracy, completeness, consistency, timeliness, validity, and uniqueness across your data supply chain. To achieve this, our engineers implement data profiling, validation, schema checks, and duplicate detection, run automated tests, and set up early alerts for quality threshold violations.

Data Platform Performance and Cost Optimization
If your data infrastructure has become slow, expensive, and difficult to maintain, SysGears’ engineers will help modernize architecture and optimize resource allocation to reduce operational friction and unnecessary costs.

Data Infrastructure Consulting
If you plan a new solution or seek to improve your existing data infrastructure, our vetted data engineers can assess your requirements, data sources, processing needs, and current system architecture to assist you with strategy and right technology selection.

Data Platform Maintenance
Our engineers can maintain your data processing workflows long-term through troubleshooting, preventive maintenance, and regular upgrades, so your platforms and pipelines remain reliable and secure.
A Portrait of a Data Engineer at SysGears
Data Platform and Pipeline Engineering Expertise

Expertise in designing, implementing, maintaining, and optimizing robust ETL/ELT pipelines, including data ingestion, transformation, validation, incremental processing, and data quality controls.
Strong understanding of distributed computing principles and hands-on experience designing, developing, and optimizing scalable batch and streaming data processing pipelines using Apache Spark.
Expertise in designing and orchestrating reliable, scalable data workflows using Apache Airflow, AWS-native services, and Databricks Lakeflow Jobs. Strong understanding of workflow dependencies, scheduling, monitoring, fault tolerance, and cross-platform integration, with the ability to select and combine orchestration tools to meet diverse architectural and business requirements.
Knowledge of the broader big data ecosystem, including message brokers, such as Apache Kafka, RabbitMQ, and AWS SQS, for event streaming and Apache Flink or Apache Spark Structured Streaming for stream processing.
Data Storage Architecture Expertise
Strong SQL proficiency, knowledge of SQL dialects, and hands-on experience administering, maintaining, and optimizing popular SQL servers like PostgreSQL, MySQL, MariaDB and others.
Expertise in selecting, designing, and integrating diverse data storage technologies, including NoSQL databases (MongoDB, Cassandra), key-value stores (Redis), graph databases (Neo4j), distributed file systems (Hadoop/HDFS), object storage (Amazon S3 and compatible solutions), and vector databases (Qdrant, PostgreSQL with pgvector). Strong understanding of their capabilities, trade-offs, and use cases, enabling the design of fit-for-purpose, polyglot persistence architectures that combine multiple storage engines to meet application and data engineering requirements.
Expertise in relational database design and data modeling, including schema design and normalization, query and index optimization, and implementing effective indexing and caching strategies.
Experience designing and implementing data lakes, warehouses, and lakehouse architectures, including storage layouts, open table formats, and efficient data organization for analytical workloads.
Programming and Software Engineering Skills
Proficiency in Python, Scala, Go, TypeScript.
Strong expertise in designing and implementing scalable, fault-tolerant distributed applications and web services using Scala (Apache Pekko, ZIO, Cats) and asynchronous Python frameworks (FastAPI, Flask, DRF, Celery), with an emphasis on concurrency, resilience, backpressure, and system performance.
Cloud Infrastructure and DevOps Expertise
Experience provisioning and managing cloud infrastructure across AWS, Azure, and GCP, including compute, storage, networking, and managed services.
Proficiency in Infrastructure as Code (Terraform), Docker, Kubernetes, Git, and CI/CD automation for reliable, repeatable deployment and operation of data platforms and applications.
Why Hire Data Engineers at SysGears

Senior Data Engineering Expertise Since 2012
SysGears has been providing data engineering services for businesses since 2012. Our specialists have experience building solutions for real-time data streaming and batched data processing from scratch, including big data software.

Experience Across Heavily-Regulated Industries
Our data engineers have a proven track record working across healthcare, finance, and govtech projects. We sign strict NDAs and ensure secure development environments for every project, including, but not limited to, permission-based access to code repositories, robust secrets management, regular vulnerability reviews and configuration hardening, along with secure office spaces and hardware.

Human-led, AI-Augmented Development
Our data engineers understand the advantages and limitations of the current state of agentic AI engineering. We can use AI for automating routine work while keeping all critical technical decisions in human hands.

Transparent Cooperation Terms
Our specialists quickly integrate with your team’s workflows and maintain transparent communication throughout the engagement. Our support team stays in contact with you to collect feedback, resolve issues, and address constraints if they arise.
Explore Our Expertise Across Recent Client Projects
Big Data Software for Dental Facilities
Challenge: Re-development of a data analytics product serving over 200 dental clinics in the US to improve data processing quality, performance, and usability.
Solution: Our team researched how the software worked with the supported CRMs, designed the data model and system interaction process, and rebuilt the system architecture around the product’s performance requirements. We also implemented data processing with Apache Spark and built functionality to present the results through dashboards and graphs.
Technology stack: Scala, Play, Kafka, Apache Spark
Challenge: Modernization of a smart mobility platform that processes and analyzes data from multiple sensors and cameras for real-time traffic monitoring, infrastructure management, and public safety. The goal was to improve data processing speed, the solution’s scalability, and customization capabilities.
Our solution: Our engineers built a microservice architecture to support faster parallel processing of IoT data streams, reduce bottlenecks, and improve resource utilization. In addition to developing new modules, our team built an IoT device management system and enabled third-party integration, with a focus on secure data exchange.
Tech stack: Scala, Play, Akka, Akka-cluster, Kafka
Movie Theater Subscription Platform
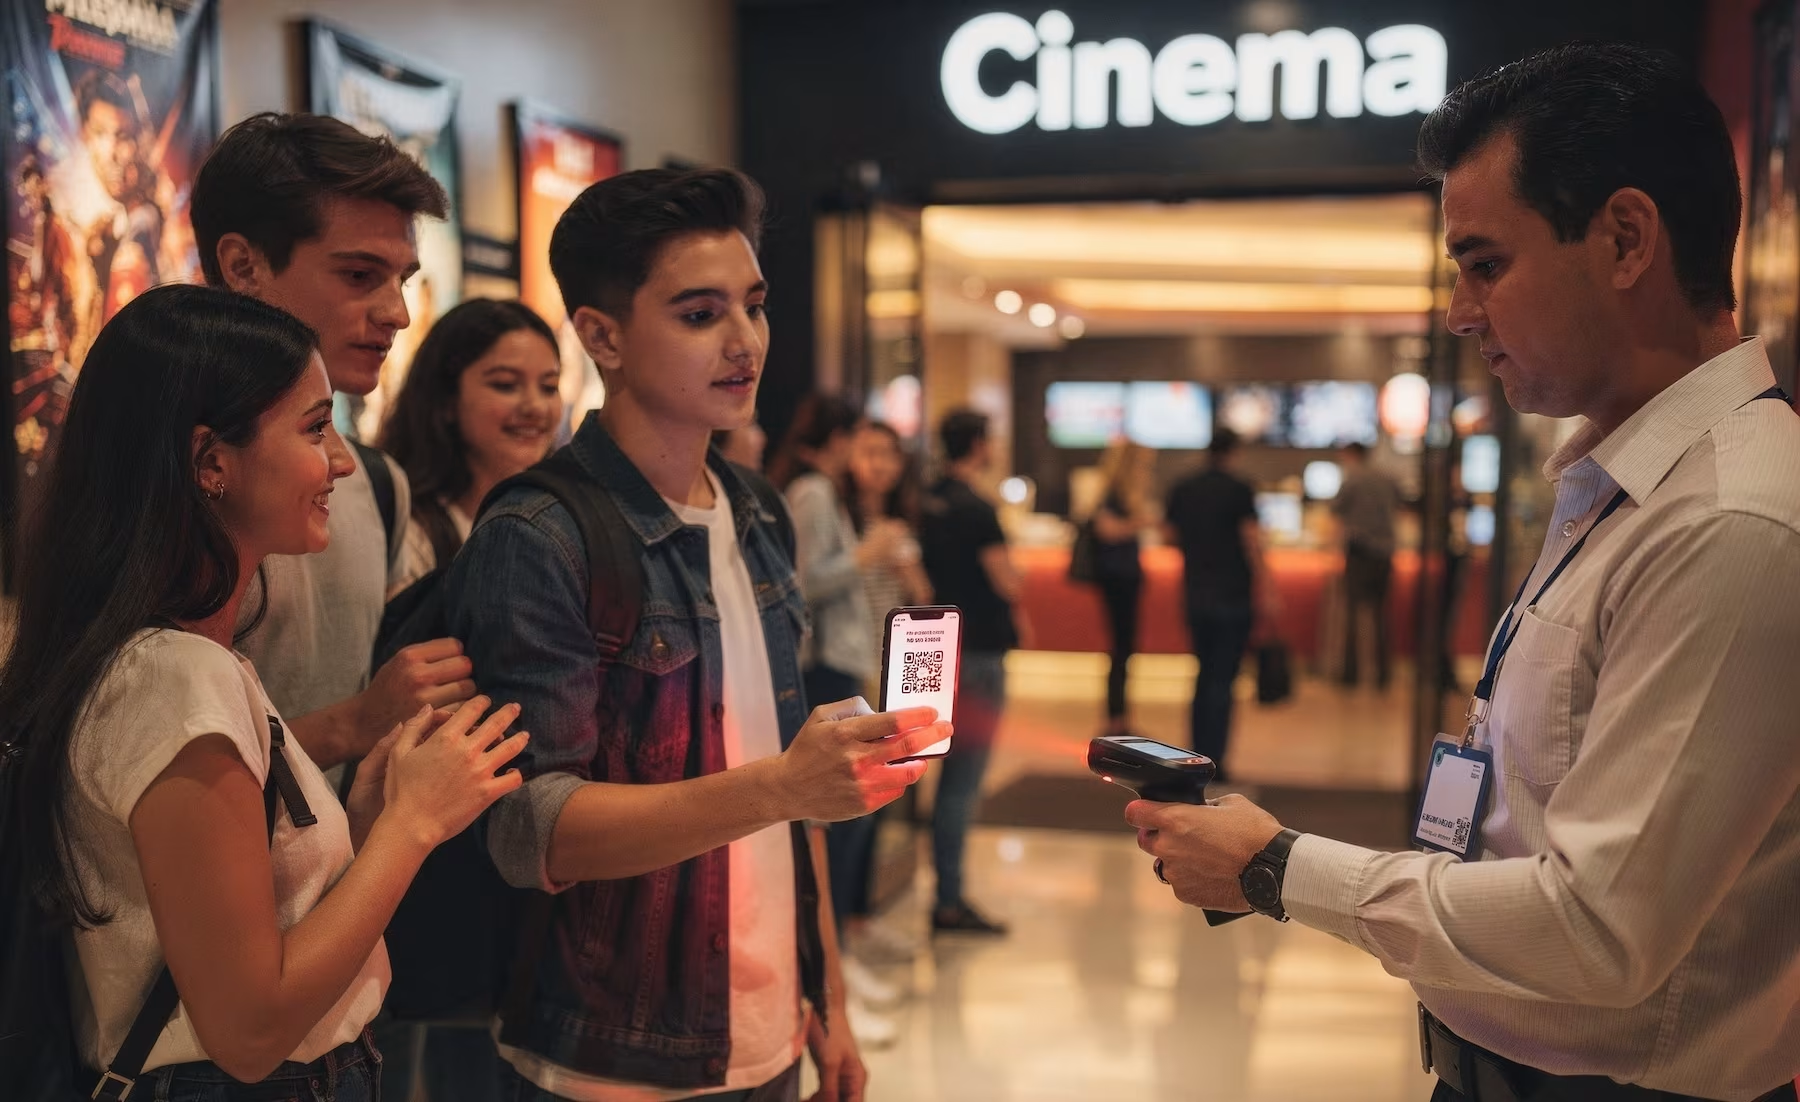
Challenge: Modernization of the microservice-based movie ticketing system that collects movie information, schedules, and showtimes from multiple external data providers. Several microservices needed a revamp to improve data processing speed.
Solution: Our data engineer refactored and optimized several ETL pipelines so mobile app users always see up-to-date information about movies. Since data freshness was critical to the service operation, event-driven ETL pipelines were built. We also developed several admin-facing API endpoints to let operational teams manage processed movie data, which would later appear in the user-facing app. This helped streamline the back-office workflows and improve control over catalog quality and consistency.
Technology stack: Scala, Play3 Framework, Pekko (actors/streams)
Our Clients on Working with SysGears

5.0

“SysGears delivered quality work in a timely fashion. Their communication was very proactive. We had daily check-ins to keep updated with the status of work.I am very happy with the results.”
VP of Product, Consumer Products & Services Company
5.0
“This company has been nothing but transparent and helpful in the development process. They are taking ownership of their code and delivering great quality, while providing a streamlined & open communication channel. I’ve worked with a handful of other vendors in the past and have never gained trust for a company like I have with SysGears.”
Moni Ali
Founder & CEO, Web & App Dev Company
5.0
“We have been working with Sysgears for the custom software development of our health tech product, and the experience exceeded our expectations. From the outset, they demonstrated a deep understanding of the healthcare industry’s complexities and the regulatory landscape. Sysgears delivered on all fronts, ensuring that the product not only met our requirements but also enhanced operational efficiency and patient outcomes. I highly recommend SysGears for any custom software development needs.”
Senior Engineering Manager, Health Tech Software Company
Tell us about your project, and we’ll match you with the right expertise from our team.
FAQ
Data engineers vs. data scientists vs. data analysts: what’s the difference and what role to hire?
Data engineers build and maintain infrastructure for collecting, storing, normalizing, and processing of data, including data warehouses, lakes, lakehouses, streams, and ETL/ELT pipelines. They ensure raw data is correctly, securely, and reliably transmitted from source systems to analytics and AI/ML environments. Hire a senior data engineer at SysGears if you need to build or modernize data infrastructure or prepare your data for further use.
Data analysts don’t build data infrastructure but translate already processed data into insights to solve immediate business problems, analyze historical trends, and create dashboards and reports for stakeholders. Hire a data analyst if you need to continuously monitor business metrics and make data-driven decisions.
Data scientists also focus on extracting meaning from clean, accessible data rather than building infrastructure for processing it. However, their responsibilities are more sophisticated than those of data analysts and require deeper math knowledge. They build and validate ML models, design experiments, and use forecasting algorithms and statistical methods for their tasks. Hire a data scientist if you need to predict customer behavior, detect anomalies, or develop personalized recommendation systems.
How much does it cost to hire a data engineer through SysGears compared to an in-house hire in the US?
According to Indeed, data engineer salaries in the United States typically range between $87,905 and $212,393 per year depending on experience, seniority, and industry, with the average of $136,640 in 2026. These figures don’t include additional expenses like recruitment, benefits, and payroll taxes.
At SysGears, our rates range from $40 to $80 per hour, depending on the data engineer’s seniority and role. We work on a time-and-materials basis, meaning the pay depends on the number of hours we spend on your project. You can hire our data engineers either full-time or part-time, change the number of hours needed, and scale the team up or down as your needs evolve.
What affects the cost to hire a data engineer: seniority, tech stack, or engagement length?
The cost to hire a data engineer at SysGears depends on seniority, experience, and the role you hire for. For example, a senior data engineer who manages other people and owns architectural decisions has a higher hourly rate than a data engineer who handles regular task implementation. The engagement length doesn’t affect our hourly rates.
Can we hire data engineers for a single initiative, like a warehouse build or cloud migration, or only long-term?
At SysGears, you can hire remote data engineers for both long-term projects and short-term initiatives. Our flexible cooperation models enable you to start with short-term and part-time engagement and later extend it into long-term cooperation, once you see that our data engineers are the right fit for your project.
How do you protect our data and credentials when remote data engineers work on production systems?
We apply a multi-level security approach to ensure data privacy throughout project implementation. As the first step, we sign a strict NDA and other additional data security agreements you request. Operationally, we establish isolated project environments, enforce permission-based access control to code repositories, and implement robust secrets management. We also conduct regular vulnerability review and configuration hardening.
Staff augmentation vs freelance data engineers: how do the risks compare?
Hiring a data engineer at a reliable staff augmentation and outsourcing company like SysGears offers significantly lower risk, less overhead, and more predictability as compared to hiring a freelancer. As your vendor, we will handle recruitment, training, and HR overhead, provide equipment and comfortable office space, as well as ensure data confidentiality and IP rights protection. In contrast, when hiring a freelancer, this overhead will be largely yours.
Boost your business with custom software
Tell us about your business needs and we’ll suggest a solution
Thank you!
We have received your request and will get back to you within 1 business day.


